Multilingual Text As Corpus Repository
Building corpora for low-resource machine translation
- Date
- 2023-10 – 2024-04
- Status
- completed
- People
- Seid Muhie Yimam (Mentor)
- Tania Saurty (Contributor)
- Raman Ahmad (Contributor)
- Ānrán Wáng (Contributor)
- Myy Tran (Contributor)
Summary
A DDLitLab-funded student project building text corpora to advance machine translation of low-resource languages.
Overview
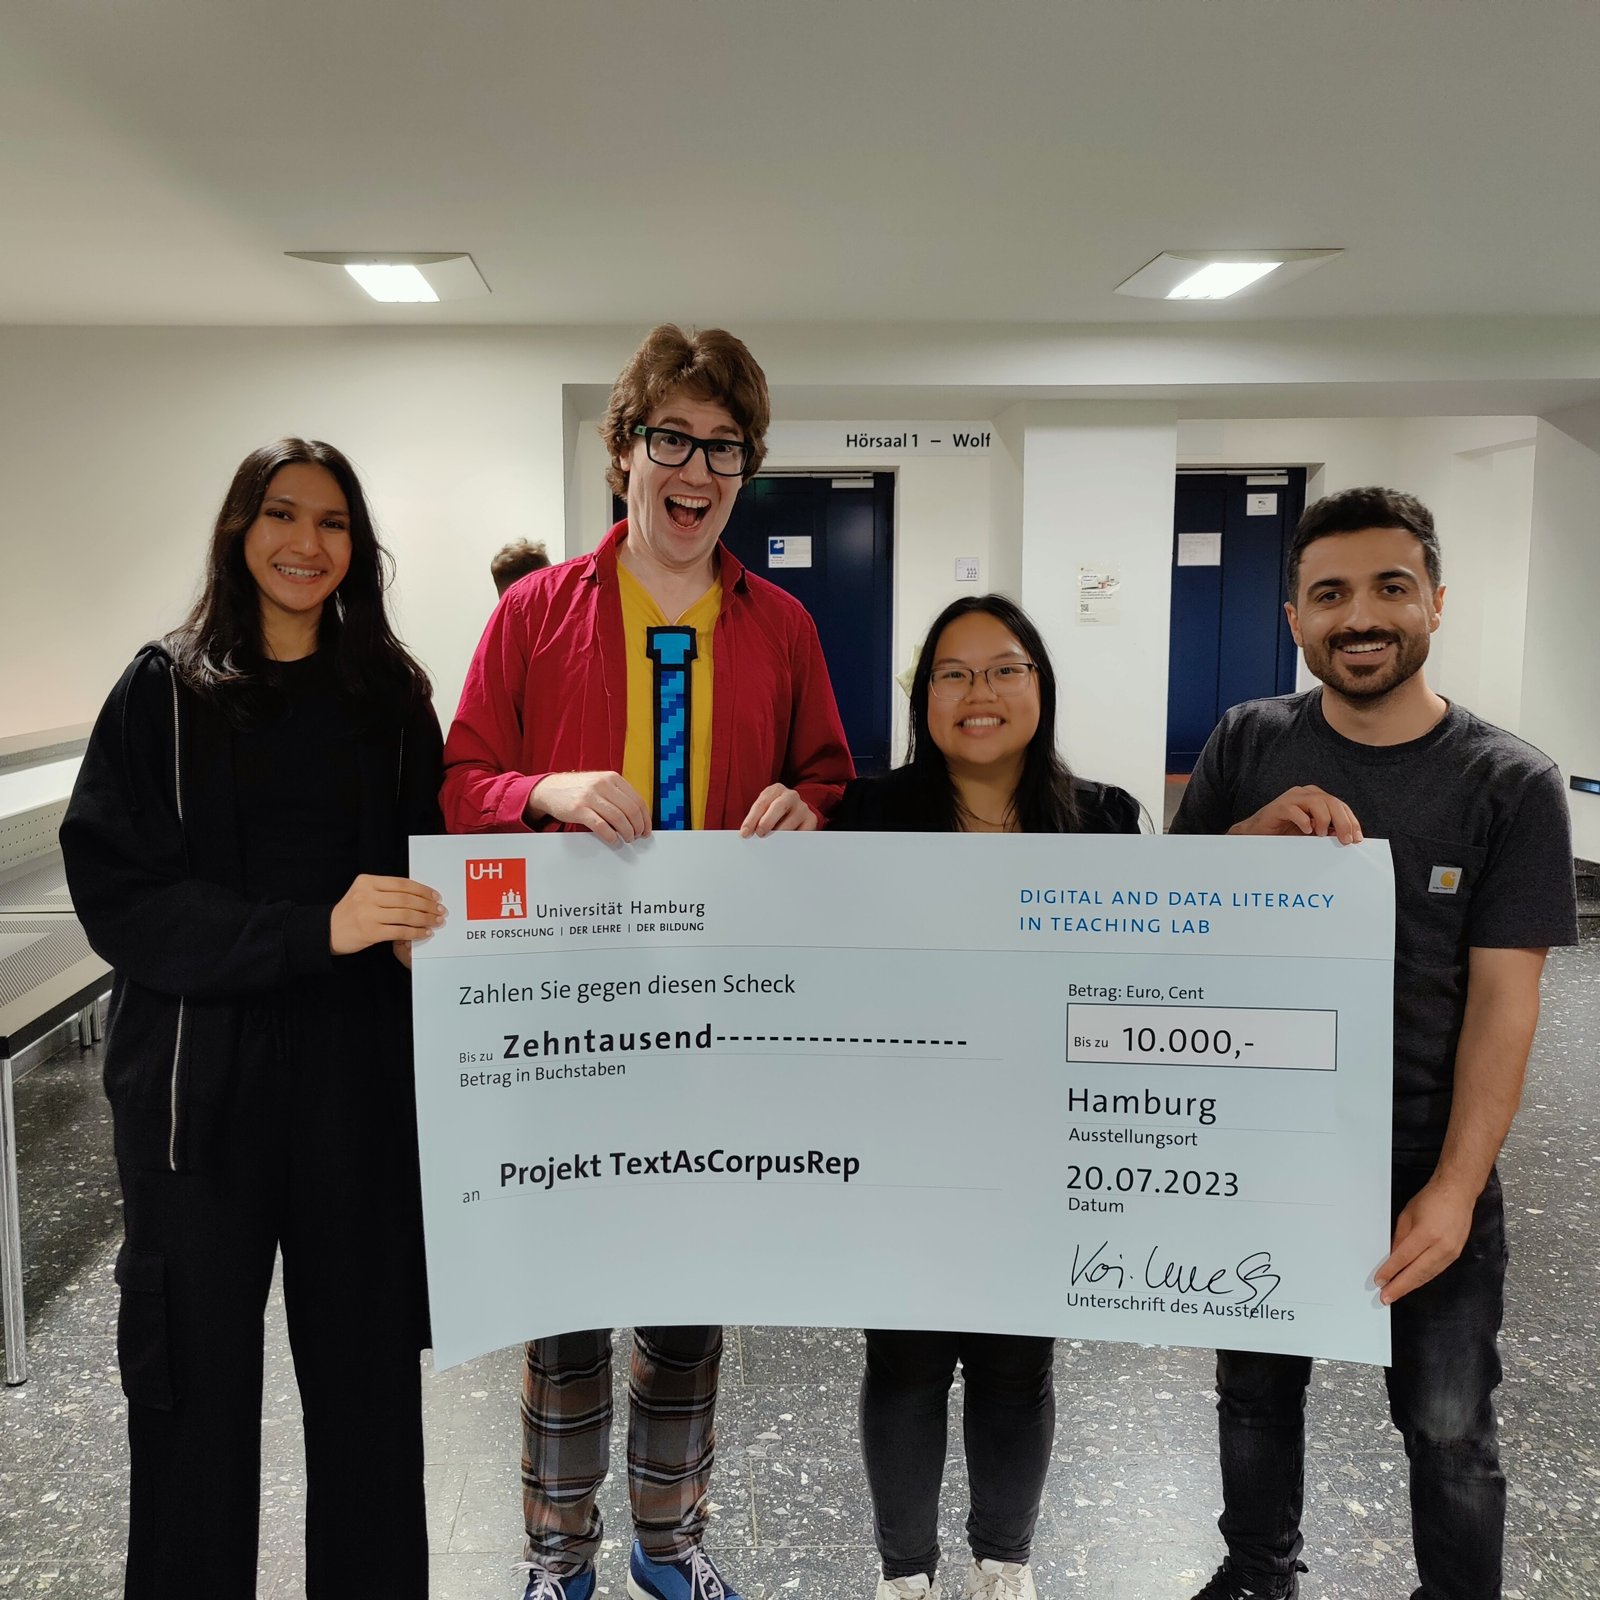
TextAsCorpusRep is a student research project that set out to build a modular, reusable repository of multilingual text corpora, with a particular focus on low-resource languages. The project was funded by the DDLitLab (D³ Data Literacy Lab) at the University of Hamburg for up to 10,000 €, under the mentorship of Dr. Seid Muhie Yimam.
Motivation
Machine translation systems for low-resource languages are held back not by a lack of algorithms but by a lack of data. Even small, carefully collected parallel corpora can dramatically improve translation quality for underrepresented language pairs. This project aimed to lower the barrier for building such corpora by providing reusable tooling and data-collection pipelines.
What We Built
- A structured repository of parallel and monolingual text data for multiple low-resource language pairs.
- Data collection and cleaning pipelines reusable across new language pairs.
- Documentation and guidelines for contributors adding data for new languages.
- A public GitHub repository so that other researchers can extend the corpus.
Outcomes
The project was presented as a poster at the EXPO 2024 student projects exposition at the BASE.CAMP creative lab in Hamburg, where it was awarded second place among all presented projects, along with a prize of 200 €. The repository remains publicly available on GitHub and continues to be a reference point for related corpus-creation efforts.
Funding
The project received funding of up to 10,000 € from the DDLitLab (D³ Data Literacy Lab) initiative at the University of Hamburg, which supports student-led data literacy projects. This was the third funding round of the programme.
Keywords
- low-resource NLP
- corpus creation
- machine translation
- data literacy
Links
Pictures
-
Project logo. -
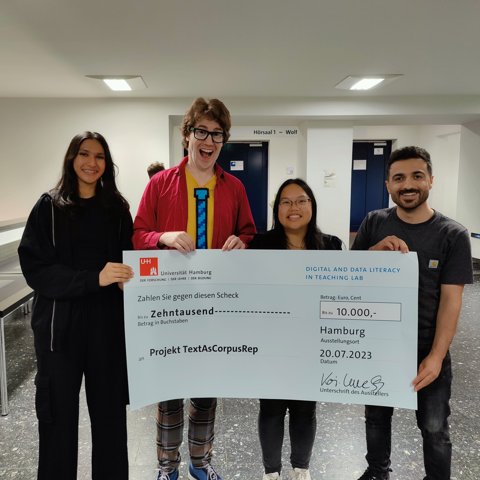
DDLitLab grant image (archived as 2023-DDLitLab-Schuler_Tran_Saurty_Wang_Ahmad-TextAsCorpusRep-Grant.jpg).